Local LLMs with Ollama
Use AgentOne's built-in Ollama provider to run open-source models locally.
What is Ollama?
Ollama is a tool that lets you run open-source AI models on your computer. This is useful if you want to:
- Use models offline without internet or API keys
- Keep data private (nothing leaves your machine)
- Avoid API costs from cloud providers
- Experiment with different models easily
AgentOne includes a built-in Ollama provider, so you can chat with models like Gemma, Mistral, Llama, and Qwen right from the app without setting up a custom provider first. You don't need an AgentOne account either.
Install Ollama and Download a Model
First, let's install Ollama and download a model to use locally.
Download and Install Ollama
Visit ollama.com/download and download Ollama for your operating system (macOS, Linux, or Windows). Follow the installation instructions for your OS. Once installed, Ollama runs as a background service. To verify the installation, open a terminal and run:
ollama --versionIf it shows a version number, you're good to go!
Download a Model
Ollama comes with access to many open-source models. Let's download Gemma 4 4B, a lightweight, fast model that's perfect for local use and can use AgentOne's tools. In your terminal, run:
ollama pull gemma4:e4bThis downloads the model (about 9.6 GB). Depending on your internet speed, this may take a while! Once complete, list your installed models to make sure everything is there:
ollama listYou should see gemma4:e4b in the list.
Make Sure the Server Is Running
On macOS and Windows, the server runs whenever the Ollama app is open. Try opening http://localhost:11434/v1/models in your browser to check (you should see some formatted data). If the server isn't running, open the Ollama app or run ollama serve.
Want a different model?
Browse the Ollama library to see models
that support tools. Just replace gemma4:e4b with any model name (for
example, qwen3:8b).
Use the Built-in Ollama Provider in AgentOne
Now let's use Ollama in AgentOne. The Ollama provider is turned on by default, and AgentOne looks for your Ollama models every time it starts.
Restart AgentOne
If AgentOne was already open, quit and reopen it so it finds your new model.
If this is your first time opening AgentOne, choose I want to use my own API keys instead during onboarding. Make sure Ollama is turned on under Local, then click Continue.
Open Provider Settings
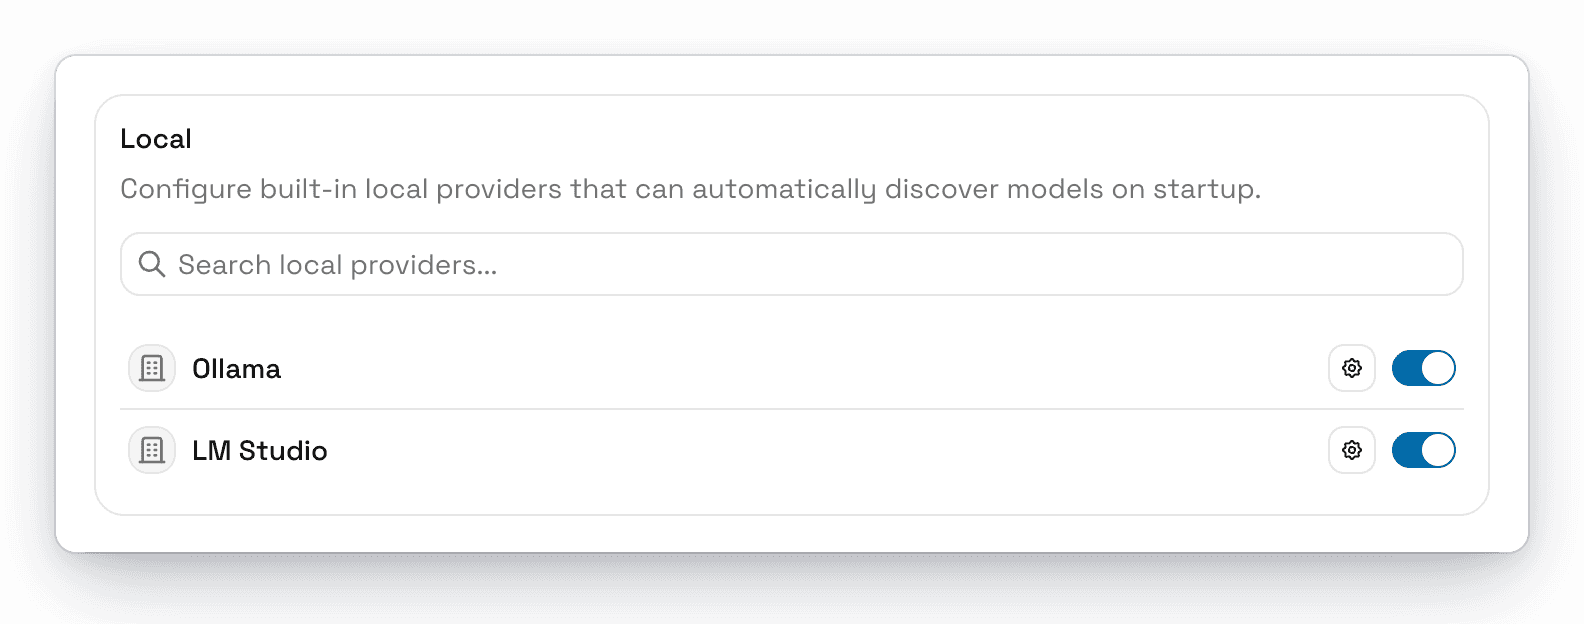
Go to Settings -> Providers and scroll to the Local section. Make sure the switch next to Ollama is on.
Check Your Models
Click the gear next to Ollama. You should see gemma4:e4b in the Models list.
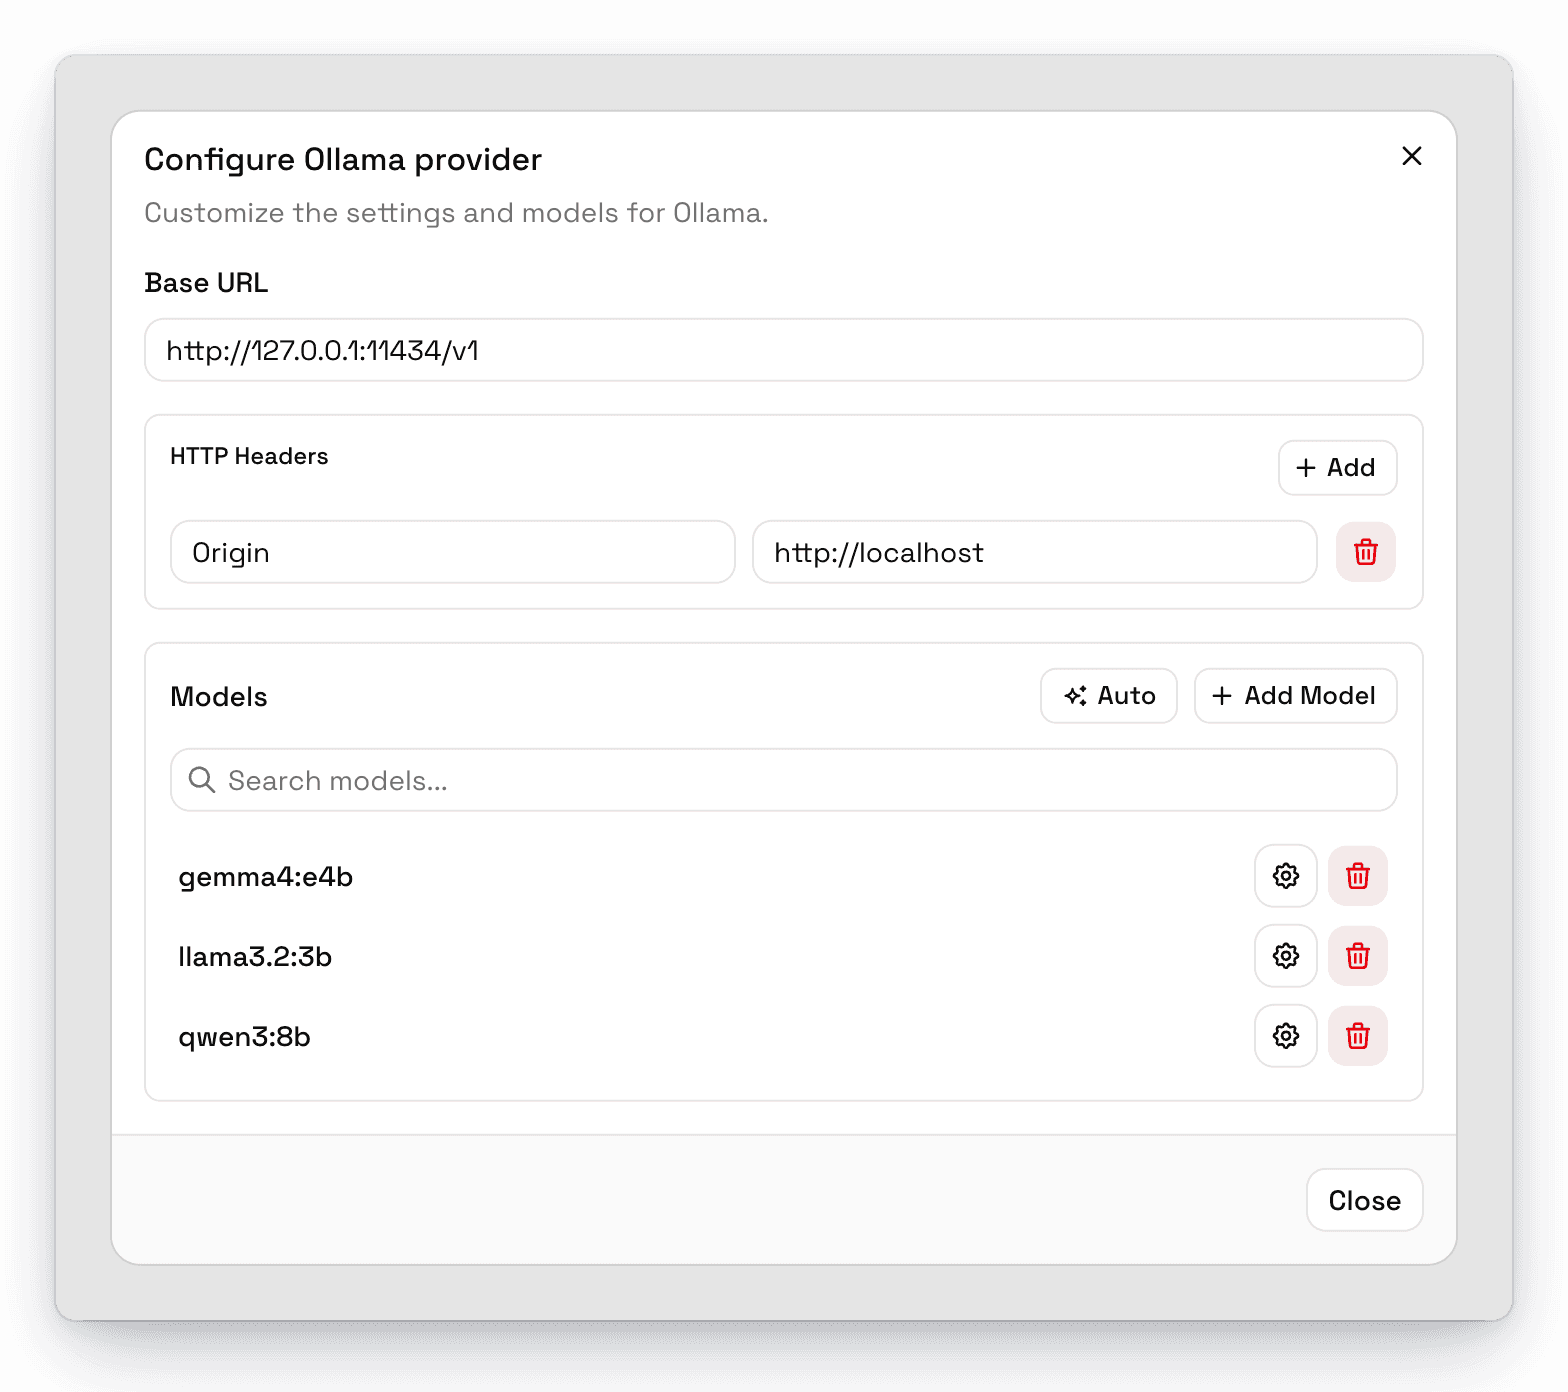
By default, Ollama uses the base URL http://127.0.0.1:11434/v1. AgentOne already sets this up for you, so you don't need to change it.
Auto-Detect Models
If your model isn't listed, click Auto. AgentOne asks your Ollama server for its models again.
Manual Fallback
If auto-detection fails, click Add Model and enter:
- Model ID:
gemma4:e4b - Display Name:
Gemma 4 (4B)(or whatever you prefer)
Leave the support switches at their defaults unless you know the model should behave differently. See Model Metadata.
Use Gemma in AgentOne
Your Ollama provider is ready. You can now:
- Switch to Gemma 4 in the model selector, under Ollama
- Chat normally, just like you would with a cloud provider, but locally
- Turn Ollama on or off with its switch in
Settings->Providers-> Local
Try something like:
What's in my Downloads folder? Group the files by type.First request might be slow
The first time you chat with Gemma, it may take a few seconds to load into memory. Later messages will be faster.
Going Fully Offline
Everything works without the internet, except tools that need it, like Search the web, Browse, and Wikipedia. You can turn those off in Settings -> Tools, or set a chat's Tool Behavior to No tools for plain chatting.
If you signed in, you can also turn on Settings -> Account -> Hide AgentOne models so only your local models show up.
Tips & Troubleshooting
Ollama Isn't Responding
- Make sure Ollama is running (look for its icon in the menu bar on macOS or the system tray on Windows), then restart AgentOne.
- Check that the base URL is
http://127.0.0.1:11434/v1, with/v1at the end andhttpinstead ofhttps.
My Model Doesn't Show Up
- Run
ollama listto make sure the model finished downloading. - Click Auto in the Ollama provider settings, or add the model manually.
Model Loading Is Slow
- Gemma 4 (4B) is lightweight, but still takes a moment to load. It gets faster after the first message.
- If you want a faster experience, try a smaller model from the Ollama library.
Usage Stats Show an Unknown Context Window
Local models often don't report their context window. Edit the model in the Ollama provider settings and fill in Context Window, so Auto-Compact can work.
Want to Try Other Models?
Visit the Ollama library, run ollama pull <model-name>, then click Auto again or add the model manually.
See Local Models for LM Studio and more options. For help, reach out on the AgentOne Forum or Discord.